DevOps and SRE notes
from production
Field notes on DevOps, SRE, and keeping production fast, reliable, and cheap. Browse the archive or subscribe via RSS.
Moving off npm
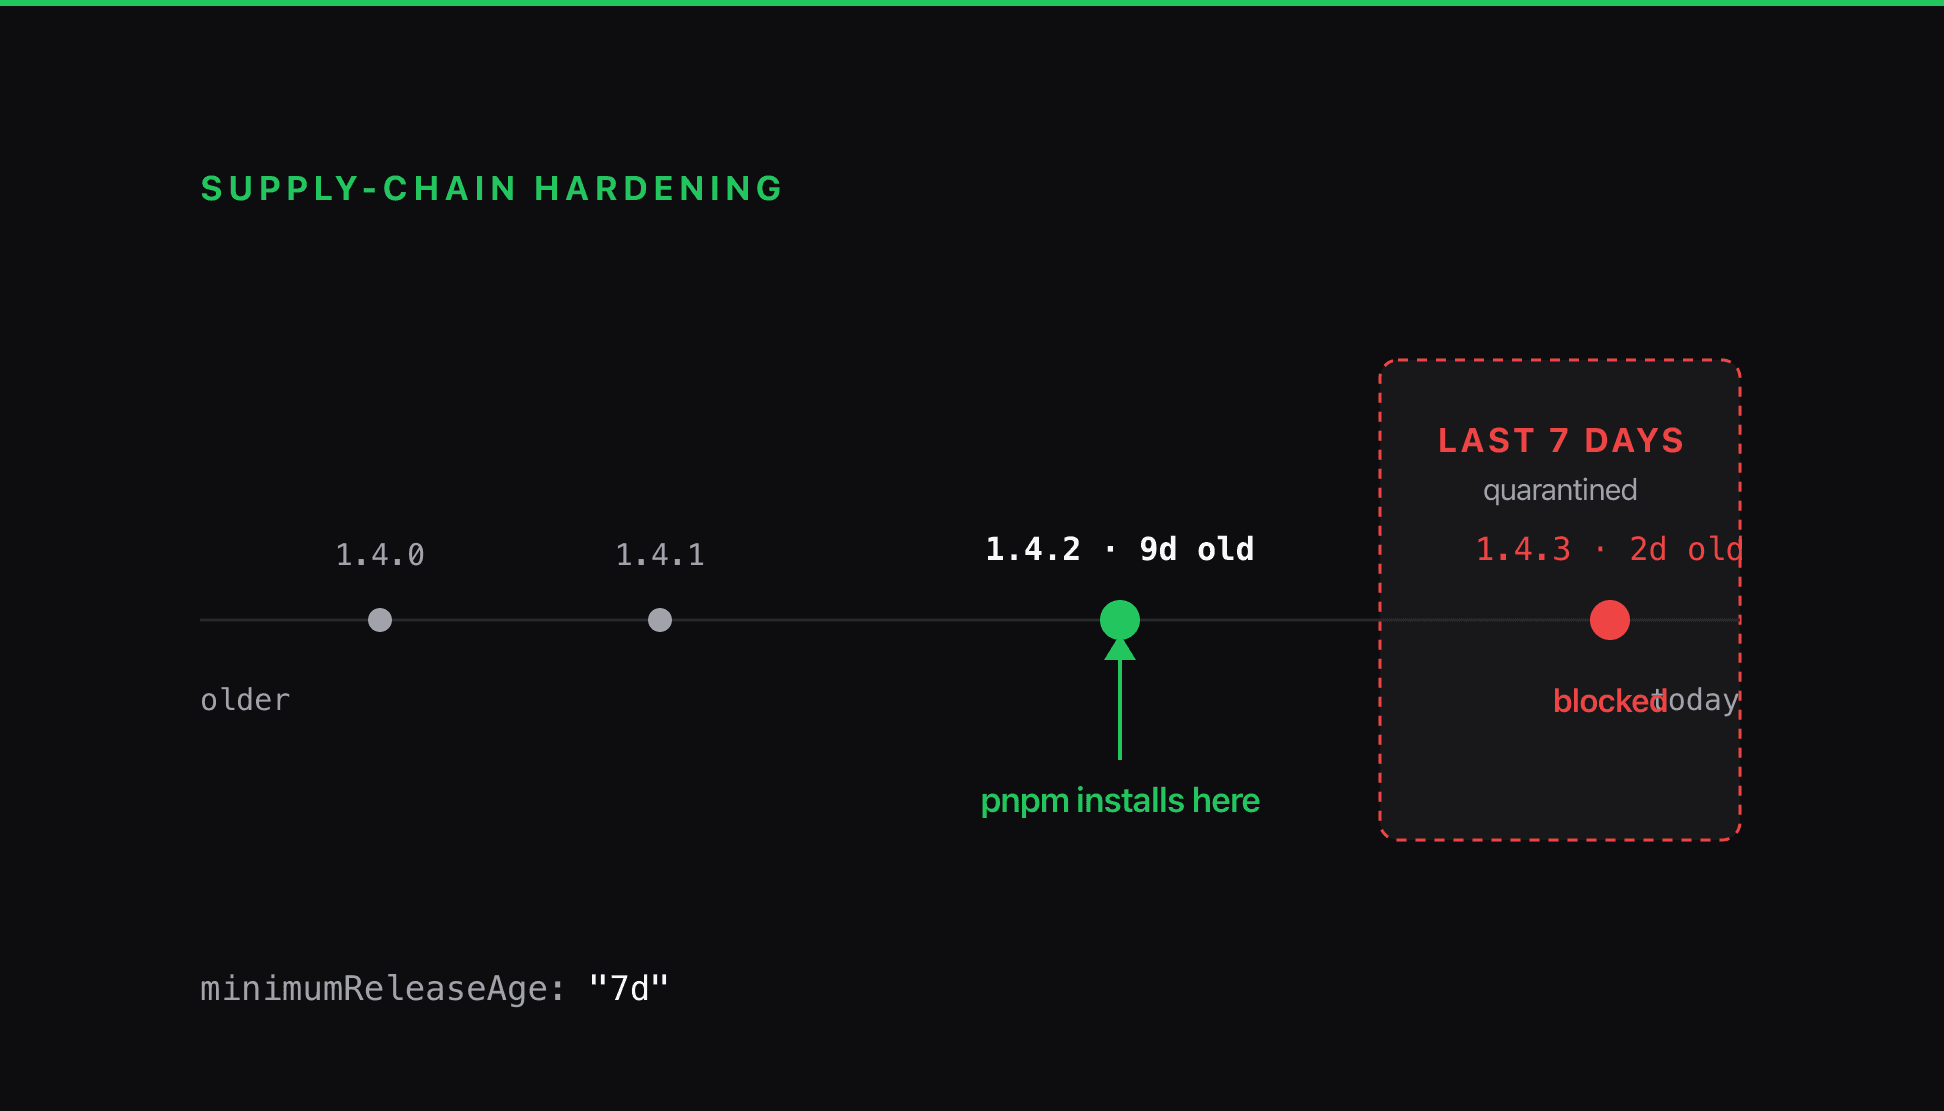
I moved a site off npm because npm 'keeps getting supply-chain attacks.' The package manager was the least important part of that sentence. A poisoned release is served the same way by every client, so the defenses that count are refusing to run install scripts and refusing to install anything published in the last week.
The Date Formatter That Froze a Production Worker
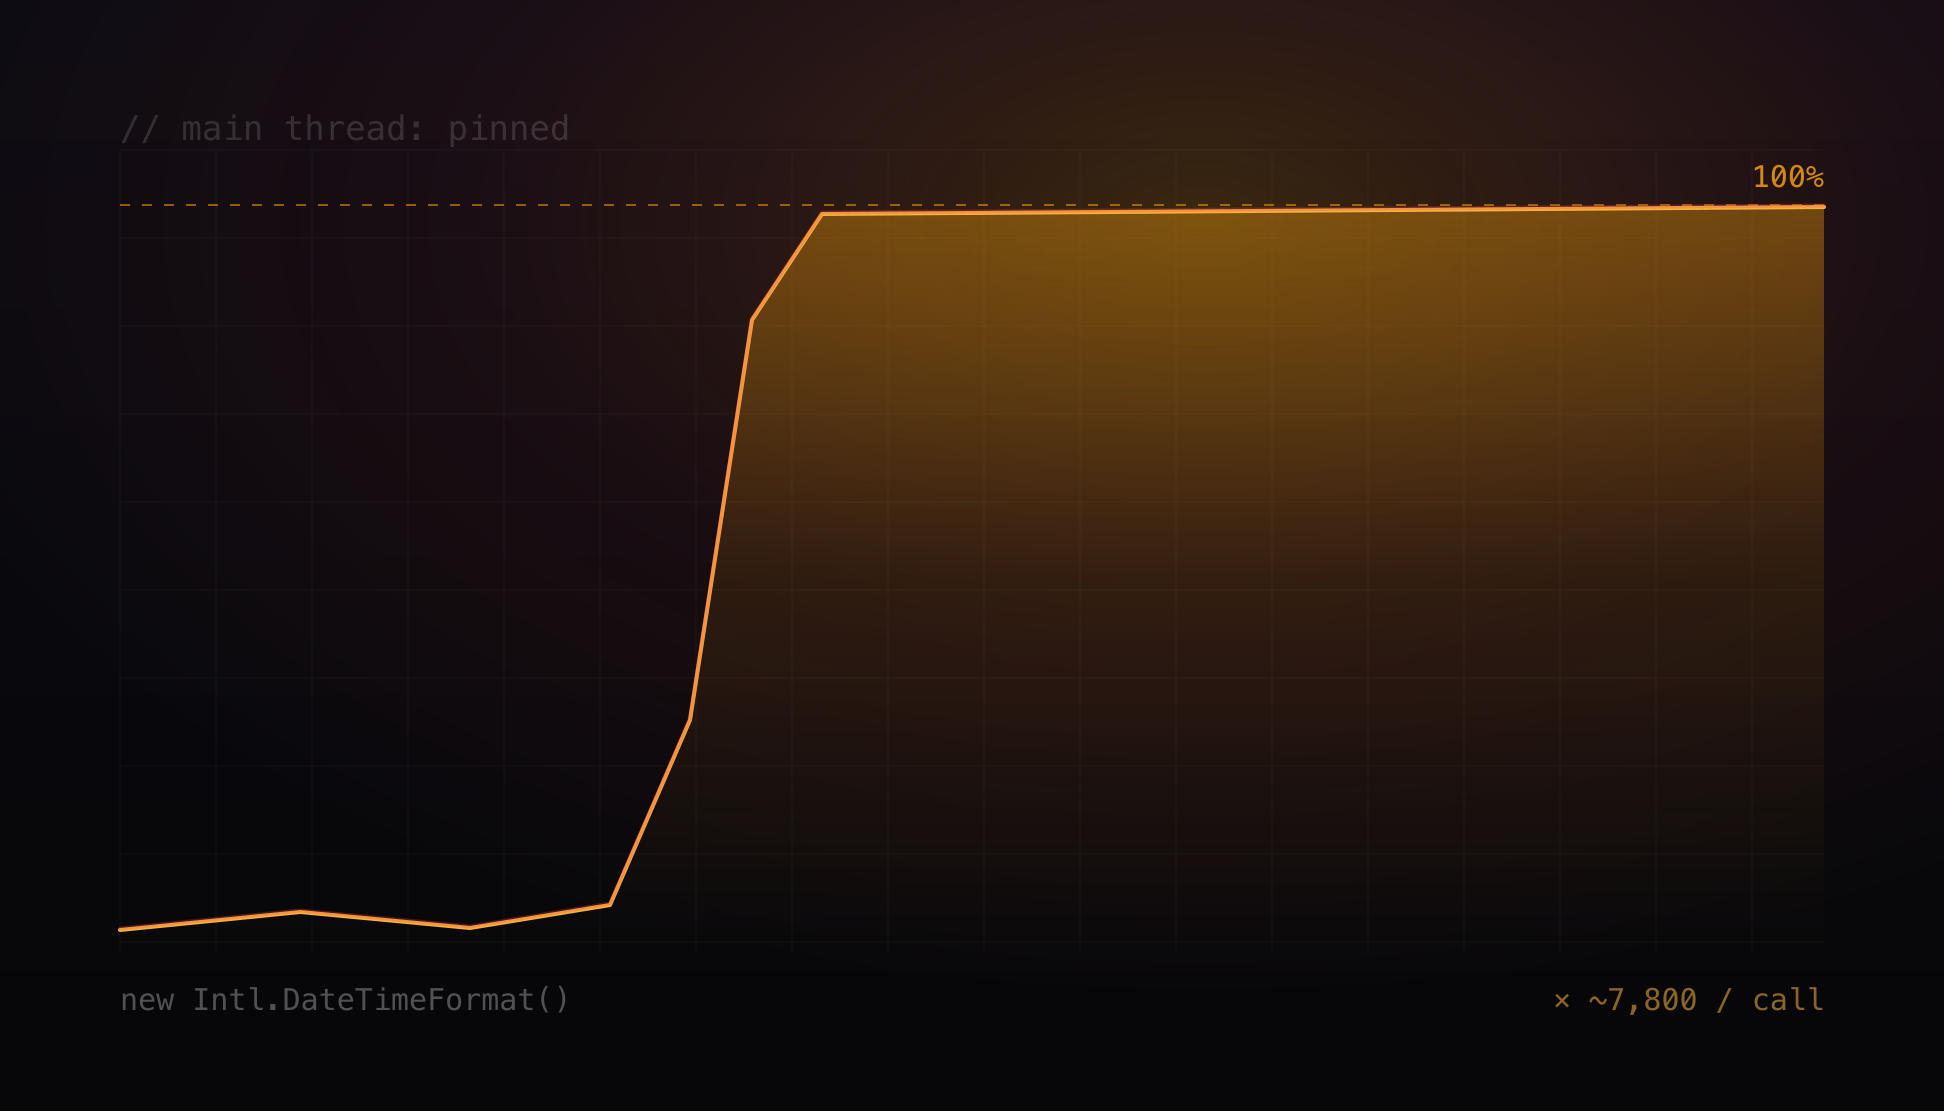
A background worker pinned at 100% CPU, every database call timing out on a pool checkout, and the pool nowhere near full. A blocked event loop makes a jammed process look exactly like an exhausted pool. The cause was a working-hours helper rebuilding a date formatter on every call, still live behind a second door.
The Download Proxy Hiding in Your Browser
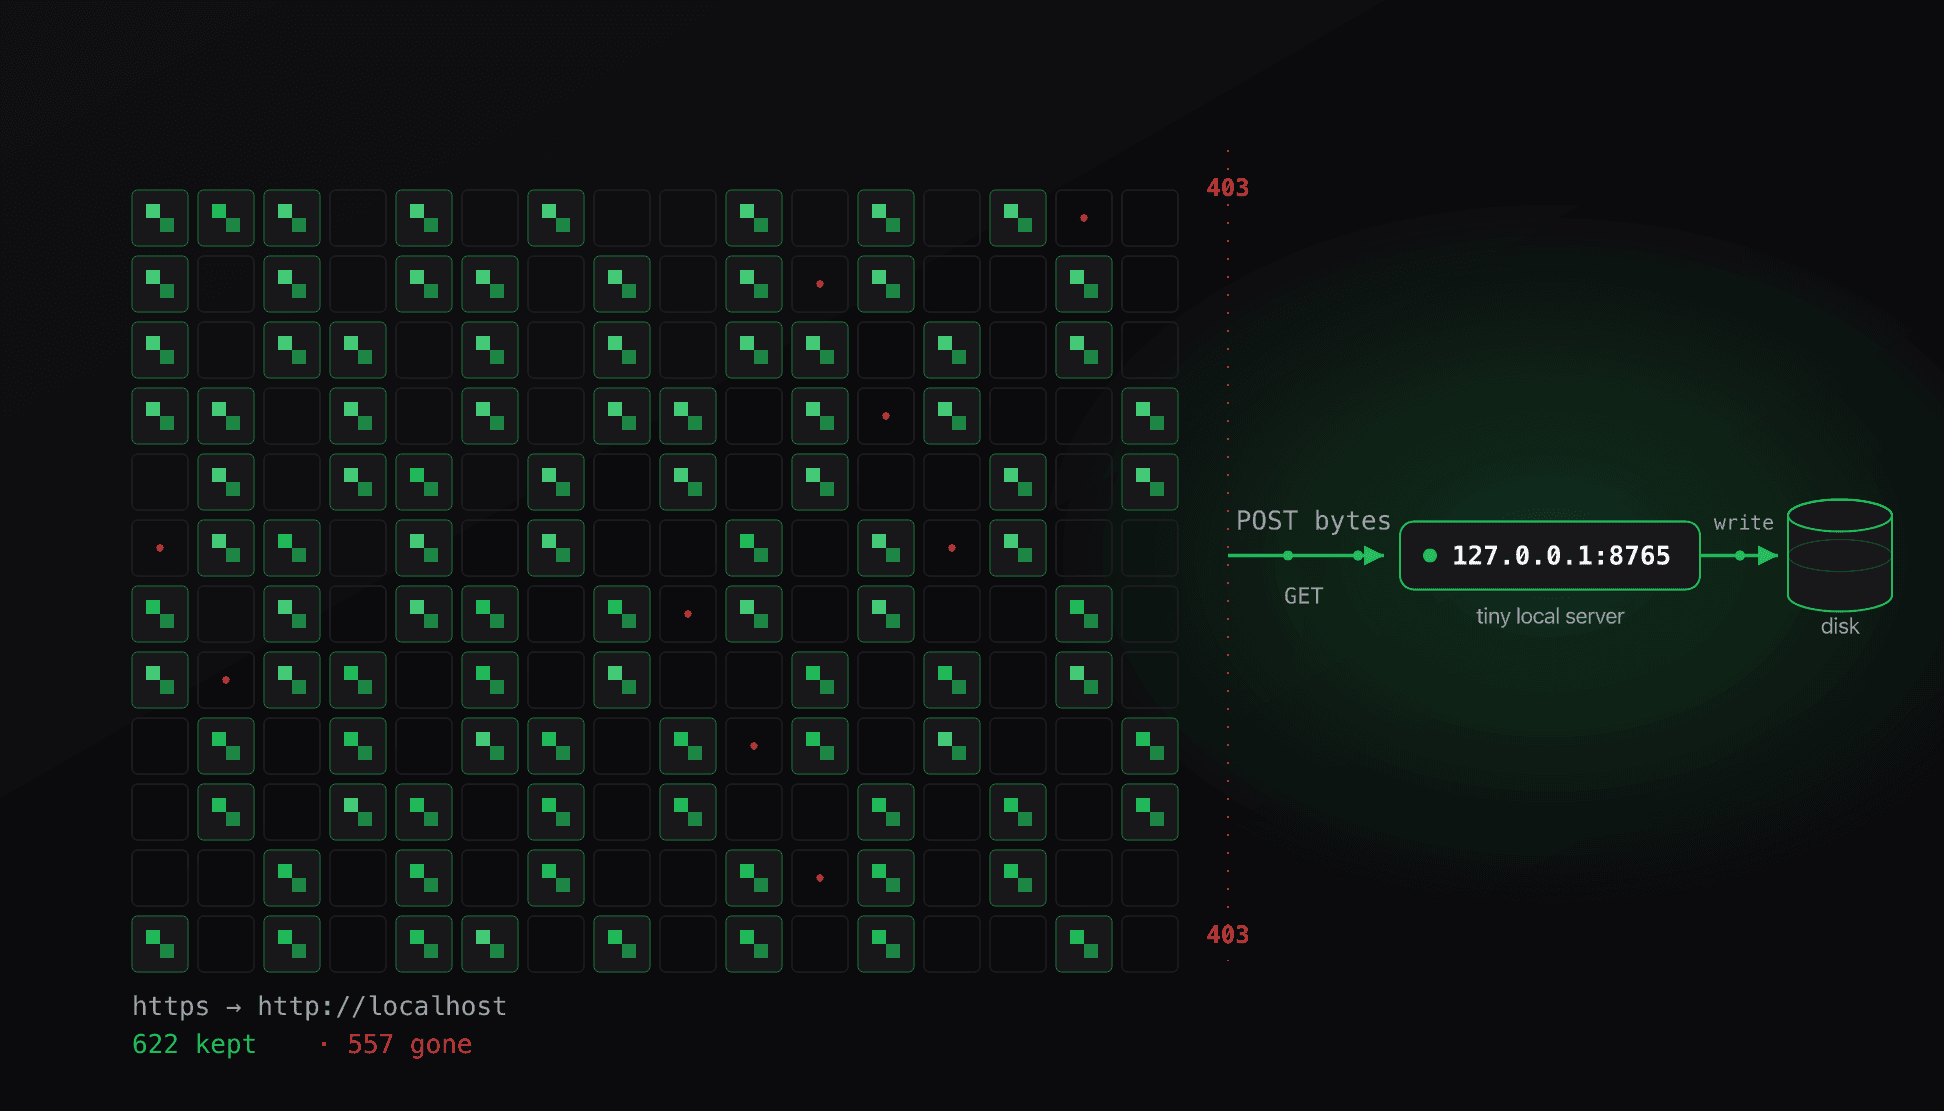
Archiving a few hundred wallpapers turned into a standoff with Cloudflare that curl and gallery-dl kept losing with a 403. The way through was a browser capability most scraping never touches, and the archive turned out to be rotting faster than I could save it.
The Boot Race That Killed 45 of 46 Consumers
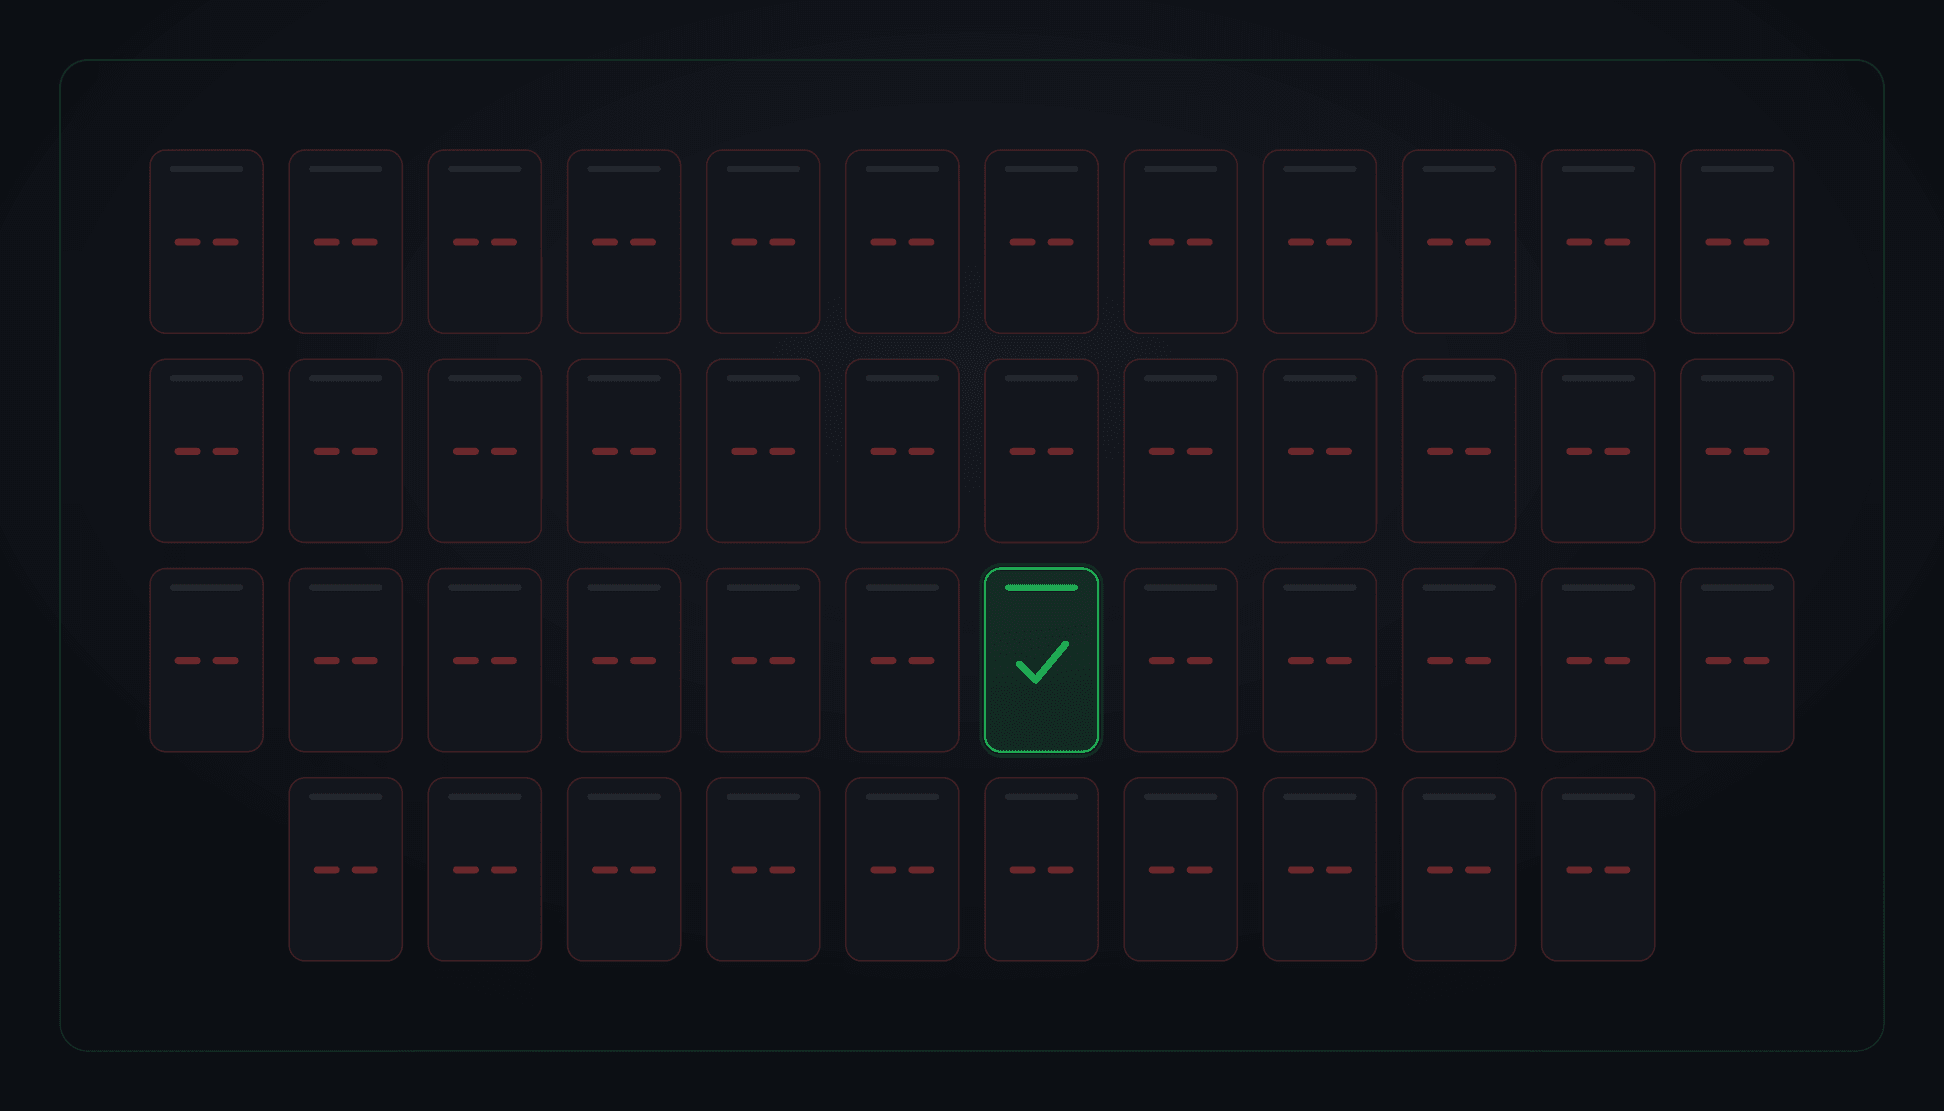
A routine host reboot brought a notification service back up in seconds (healthy, green, 200 OK) while 45 of its 46 message-queue consumers were dead and had been since the moment it started. The broker's AMQP listener opened 38 seconds after boot; every consumer had already dialed once, hit ECONNREFUSED, and disabled itself without retrying. The health check couldn't see any of it, because it watched the process, not the work.
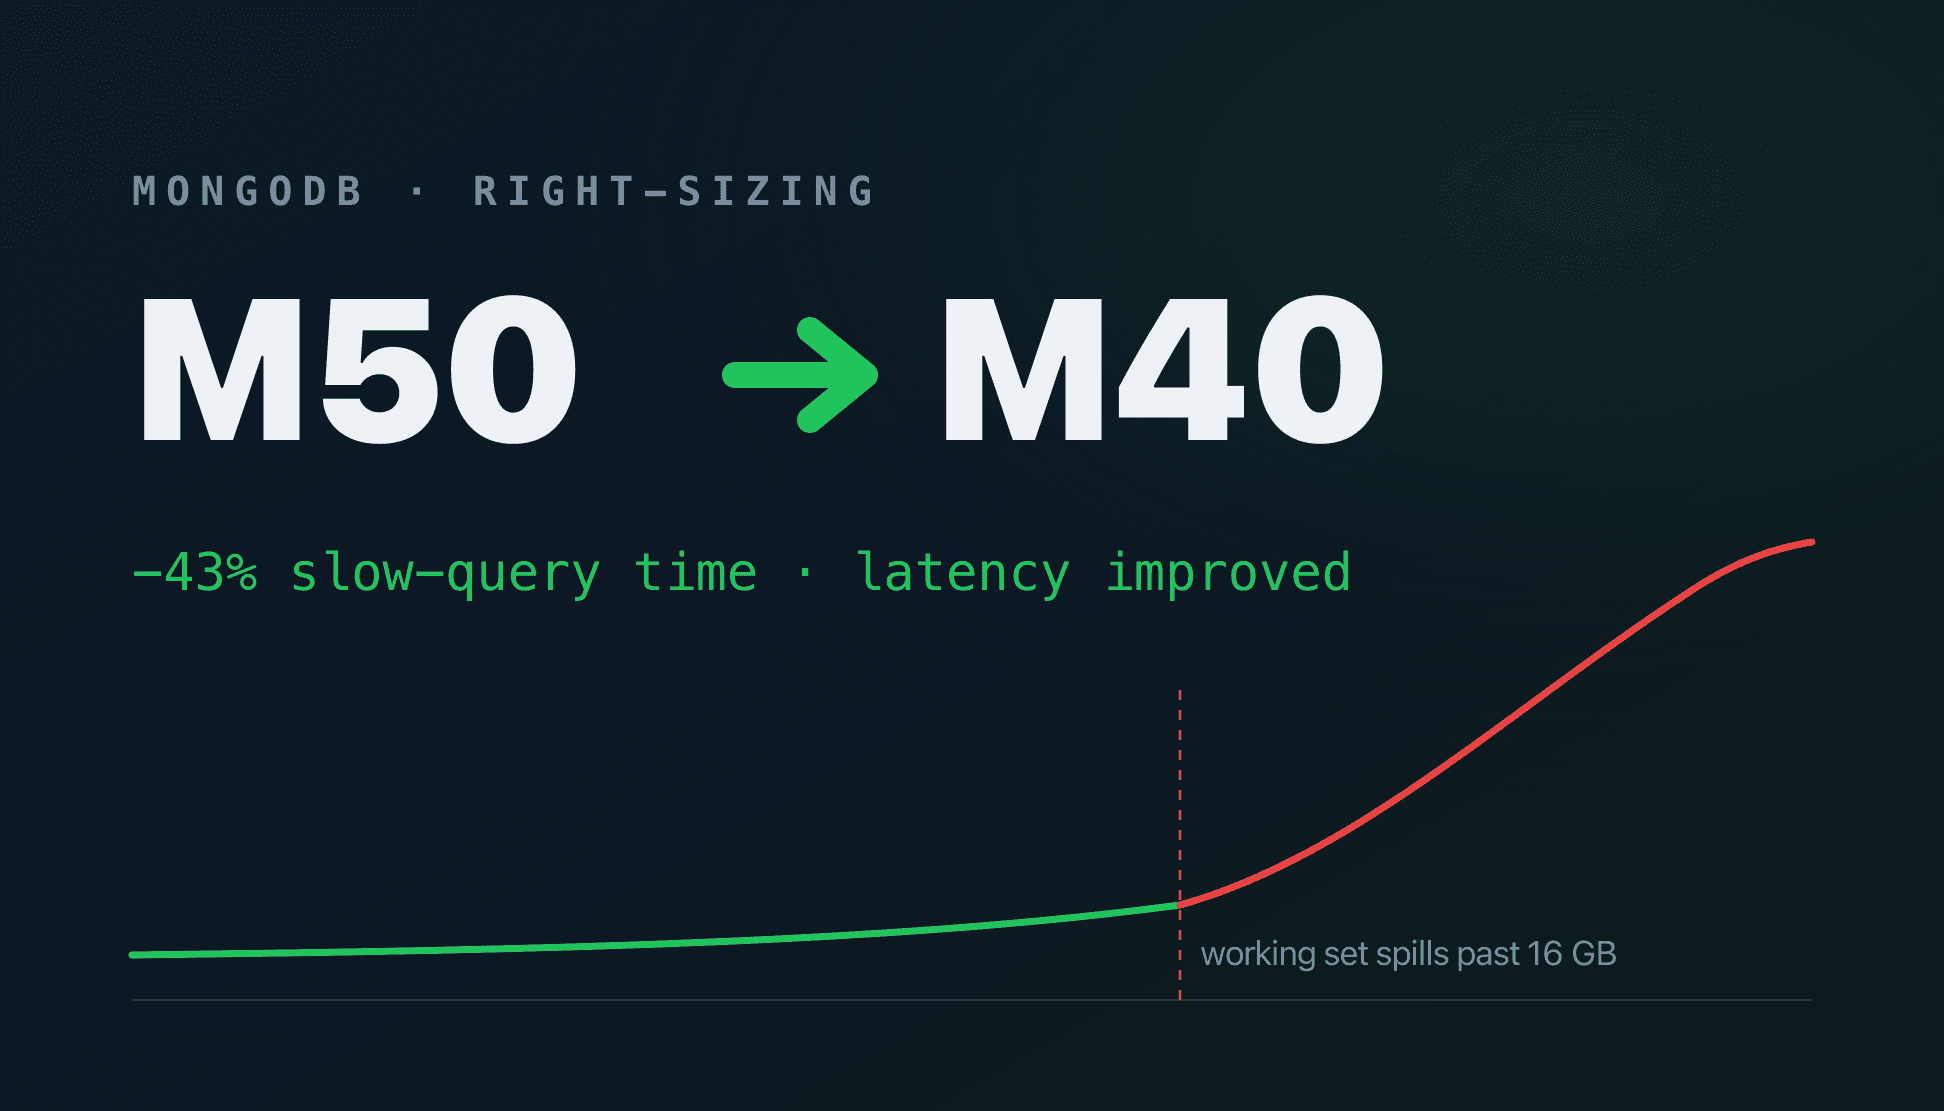
Right-Sizing a Production MongoDB Cluster: M50 → M40
You can't just click "downgrade" on a production database. Here's the log forensics, index surgery, and aggregation rewrites that shrank the working set enough to take a MongoDB Atlas cluster from M50 to M40, a full tier down, slow-query time down ~43%, and latency that improved through the cut.
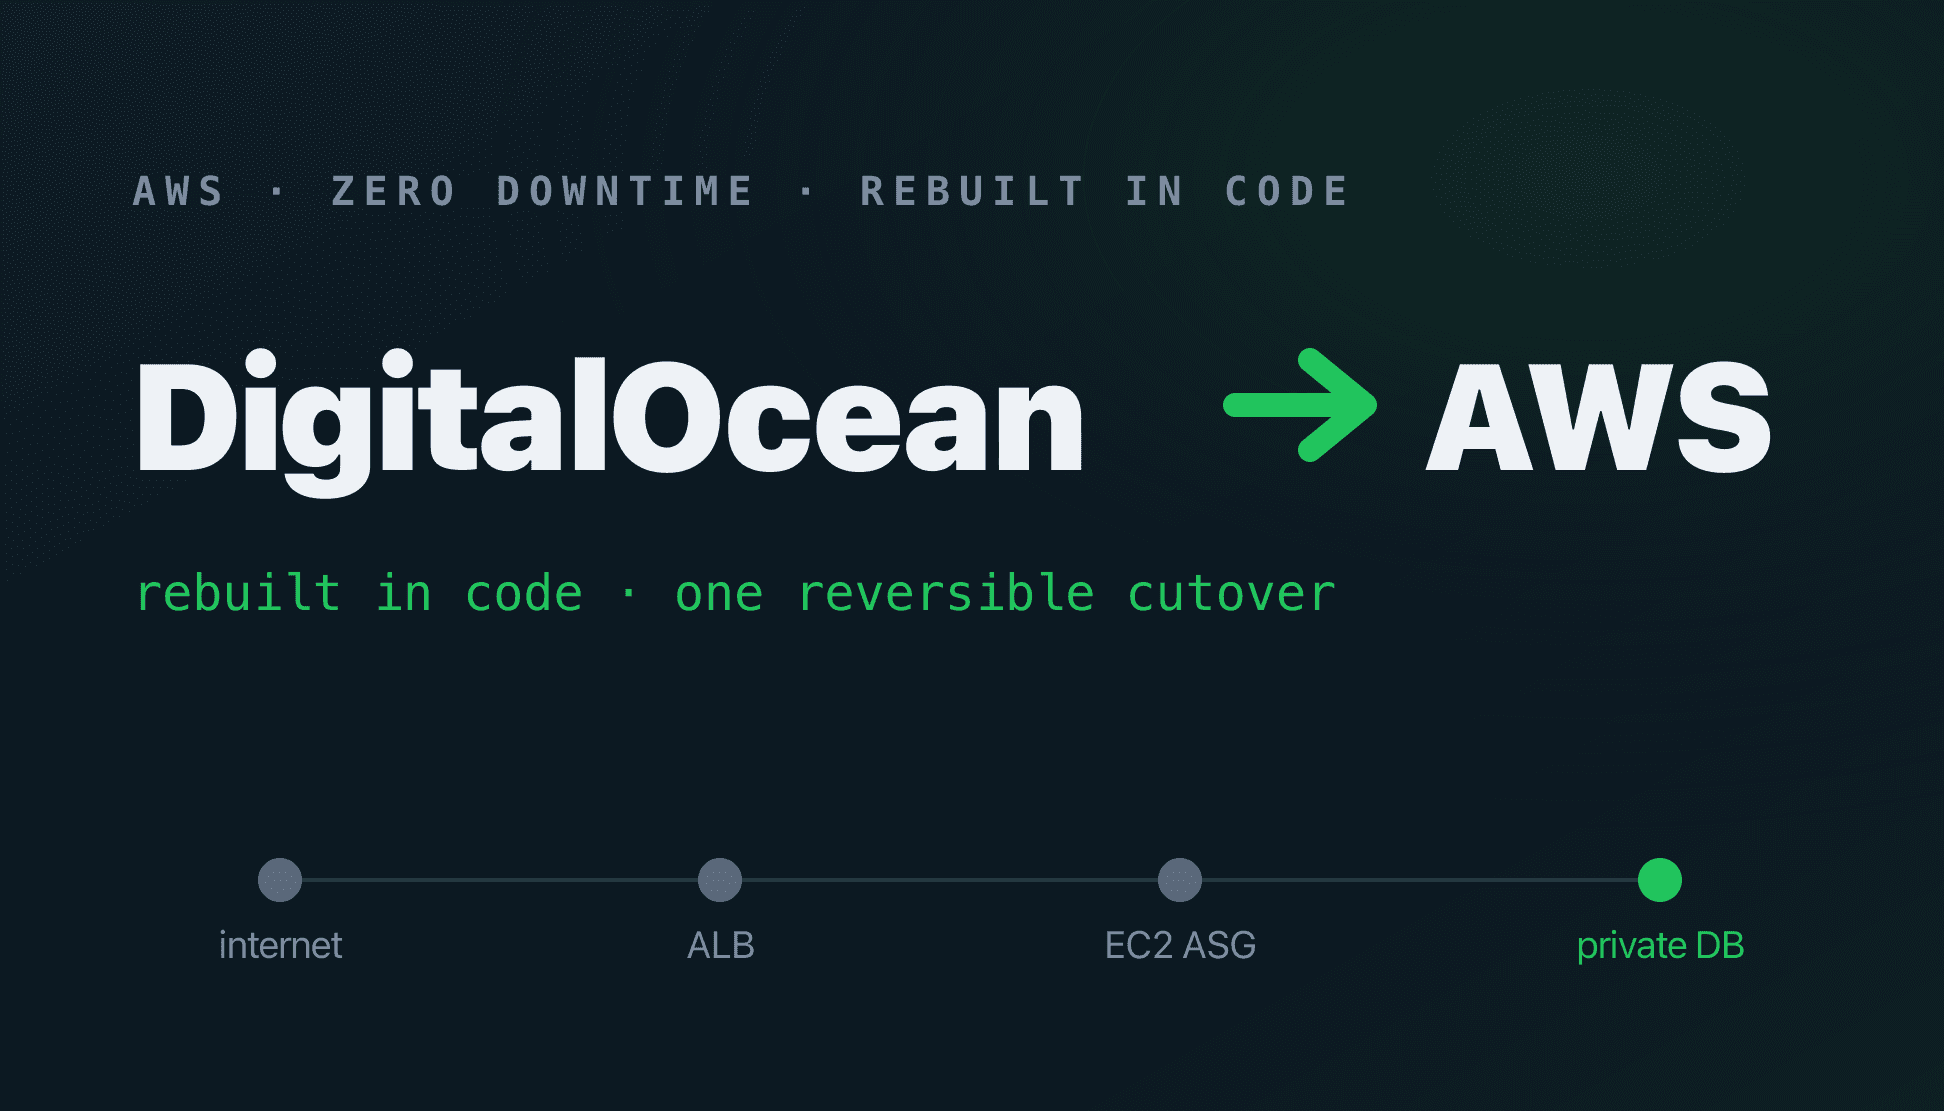
A Zero-Downtime DigitalOcean → AWS Migration (50k Users)
Moving a live 50,000-user production platform off DigitalOcean and onto AWS without a single customer noticing: rebuilt entirely in Terraform and flipped over with one reversible DNS cutover, with the old stack kept warm as a real rollback net.
The "DELIVERED" That Never Arrived
A notification database was reporting DELIVERED for mail that never arrived. Delivery was recorded the instant SES accepted the API call, not when the message landed, so ~37,000 bounces a day were filed as successes, hiding a steady 52% bounce rate and a bill quietly running at double. The fix was to stop trusting acceptance and wire the real delivery events back on.
The Logged-Off Desktop That Killed 62 of 66 Production Processes
62 of 66 processes on a single Windows box went dark, while disk, RAM, and CPU all read green. The real cause was a runaway terminal exhausting the Windows commit limit, crashing the desktop compositor, and logging off the session every process lived inside. An incident I debugged end to end over AWS SSM, with no RDP.